Apps built quickly, whether by a small team or with an AI builder such as Bolt, Lovable or Cursor, tend to fail in the same few places once real users, data and money arrive: one customer seeing another’s data, duplicate payments, and edits that silently vanish. Most of these can be found in a short, focused review and fixed at the root, which is why the usual answer is a stabilization pass, not a rebuild.
None of these is exotic. They share one cause: a demo proves the happy path and never exercises the unhappy ones. For each, here is the mechanism and a check you or your developer can run.
Authorization lives in the UI, not the backend
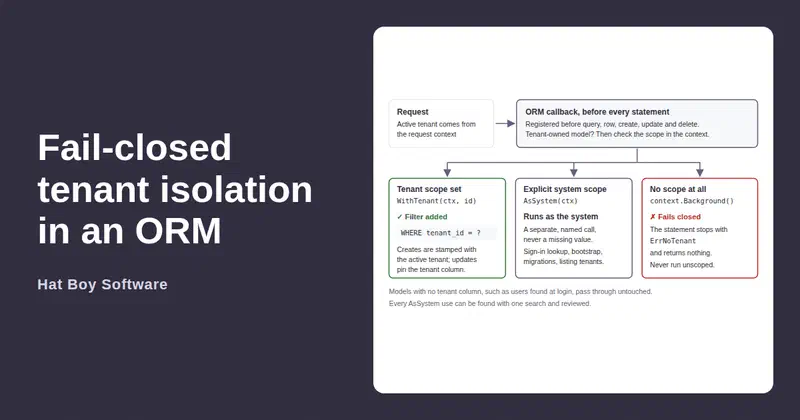
This is the most common finding and the most serious. The interface hides the admin button from non-admins, so the app looks secure, but the backend function behind that button accepts any request that reaches it.
In one assessment, now a public case study, about 1 of ~80 backend functions verified the caller’s identity, and the database rules resolved to allow read and write for anyone. Withdrawal, bank-linking and payment endpoints were effectively open. The front end worked as designed; it just was not what enforced access.
Check it yourself: take a request your browser sends for a privileged action, replay it with no session or with a low-privilege user’s token, and see whether the server refuses. Every function that touches data or money should establish who is calling first.
Row-level security is missing or over-broad
On Supabase and other Postgres-backed stacks, the browser often talks to the database directly using the project’s public key (called the anon or publishable key). That key is meant to be visible; it is safe only because row-level security (RLS) decides which rows each user can reach. The other key, the service_role or secret key, bypasses RLS entirely and must never appear in front-end code. Searching the built app for it is a quick check.
Where RLS is the boundary, we usually find one of three problems: tables with RLS never enabled, policies written as using (true) to make an error go away, or policies that check that a user is signed in but not which organization the row belongs to. Two queries find most of it:
-- tables in the public schema with RLS turned off
select tablename from pg_tables
where schemaname = 'public' and not rowsecurity;

-- policies that allow every row
select tablename, policyname, cmd from pg_policies
where qual = 'true' or with_check = 'true';
Then test isolation the way an attacker would: create two test organizations, sign in as a user in organization A, and use that user’s token against the same API the app uses to read, update and delete organization B’s rows by ID. The correct result is zero rows affected every time. Repeat for file storage, which has its own access policies.
Payments without idempotency keys
A payment call that times out has an unknown outcome: the money may or may not have moved. If the app or a background job retries it without an idempotency key (a unique ID that tells the processor “this is the same request again”), the processor treats the retry as a new payment. In the same case study, no transfer carried an idempotency key, so a network retry could send a duplicate ACH transfer.
The fix is mechanical: generate one key per business intent (this payout, for this invoice), save it before calling the processor, send it on every attempt, and de-duplicate incoming webhooks by event ID. Stripe and Dwolla both accept an Idempotency-Key header for this purpose. Both also expire keys after about 24 hours, so your own stored record, not the processor, is what stops a retry made days later.
Lost edits from optimistic updates and autosave races
“My changes don’t save” is rarely one bug. The usual mechanisms:
- Optimistic updates with silent failures. The UI shows the new value immediately and never checks the write. On Supabase, an update or delete that RLS filters out does not raise an error; it succeeds with zero rows changed, so nothing tells the user.
- Autosave races. Two saves are in flight, the older one lands last, and it overwrites the newer data. Sending the whole record on every save makes it worse, because stale copies of unrelated fields ride along.
- Uploads that report success early. The file upload appears to finish, but the record linking it to the user’s profile is never written.
The fixes are to confirm the row count on every write, send only changed fields, version saves (an updated_at or version check on update), and show failures to the user.
Security features that exist only on screen
Some features look complete in the interface and do nothing behind it. In the same assessment, a multi-factor confirm endpoint always returned “confirmed” and the send-code endpoint sent nothing. A “money-out” feature wrote a bookkeeping record and returned a hard-coded balance without moving any money.
They survive because they demo perfectly. Try to make them fail: enter a wrong MFA code, request a payout and check the processor’s dashboard, reset a password and confirm the old one stops working.
Secrets in the repository
Payment, email and bank-linking keys committed to git are common, and deleting the file does not remove them from history. Order matters: rotate the key at the provider first, then purge history, then move secrets into the platform’s secret store. A scanner such as gitleaks or trufflehog run across full history is a quick first check.
No visibility into real usage
Many apps reach beta with no way to answer “is anyone using this, and where do they get stuck?”. Errors go to the browser console and the team learns about problems from users. Server-side error tracking, a handful of named product events and a log of failed writes turn beta feedback from anecdote into evidence.
Lock-in to the builder
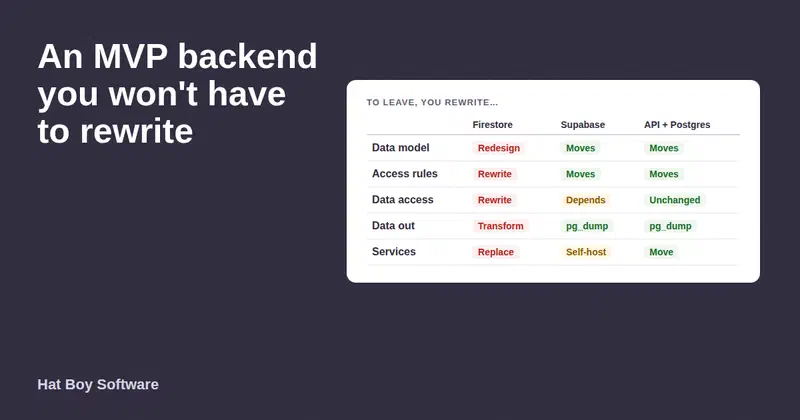
The last class is ownership. The app runs, but only inside the tool that built it: the schema was changed by hand in a console, settings live only in the builder, and there is no documented way to deploy anywhere else. The remedy is schema migrations in the repository, a written list of every environment variable and external service, and a deployment path that someone other than the original builder can run.
Why this rarely means a rebuild
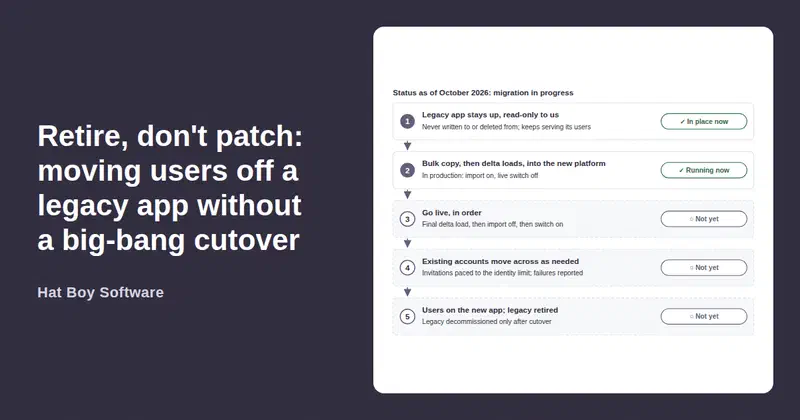
Every class above has a targeted fix: one enforced authorization boundary, tested RLS policies, keyed payment calls, versioned saves. The product logic, the UI and most of the code stay. A rebuild is warranted when the data model itself is wrong, and even then a staged migration usually beats a rewrite. Measured, not assumed: find out which situation you are in before deciding.
How we can help
Our Stabilization Assessment is a fixed-fee senior review of data access and row-level security, broken flows, lost data, visibility, and deployment and hand-off. You get a findings report and a prioritized fix list, and the plan is yours to act on with us, another team, or on your own.